

On this page
Qwen 3.6 35B-A3B runs on an Apple silicon Mac with 24 GB of memory or more. Off Grid AI Desktop runs it for free and offline. It’s a mixture-of-experts model, so it needs the memory of a 35B, but only 3B parameters work on each token, which makes it quick to reply.
On 24 GB, use a 3-bit file of about 14 GB. On 32 GB, a 4-bit file of about 19 GB. The standard 4-bit download (23 GB) runs well from 36 GB.
Download Off Grid AI Desktop (free, no account)
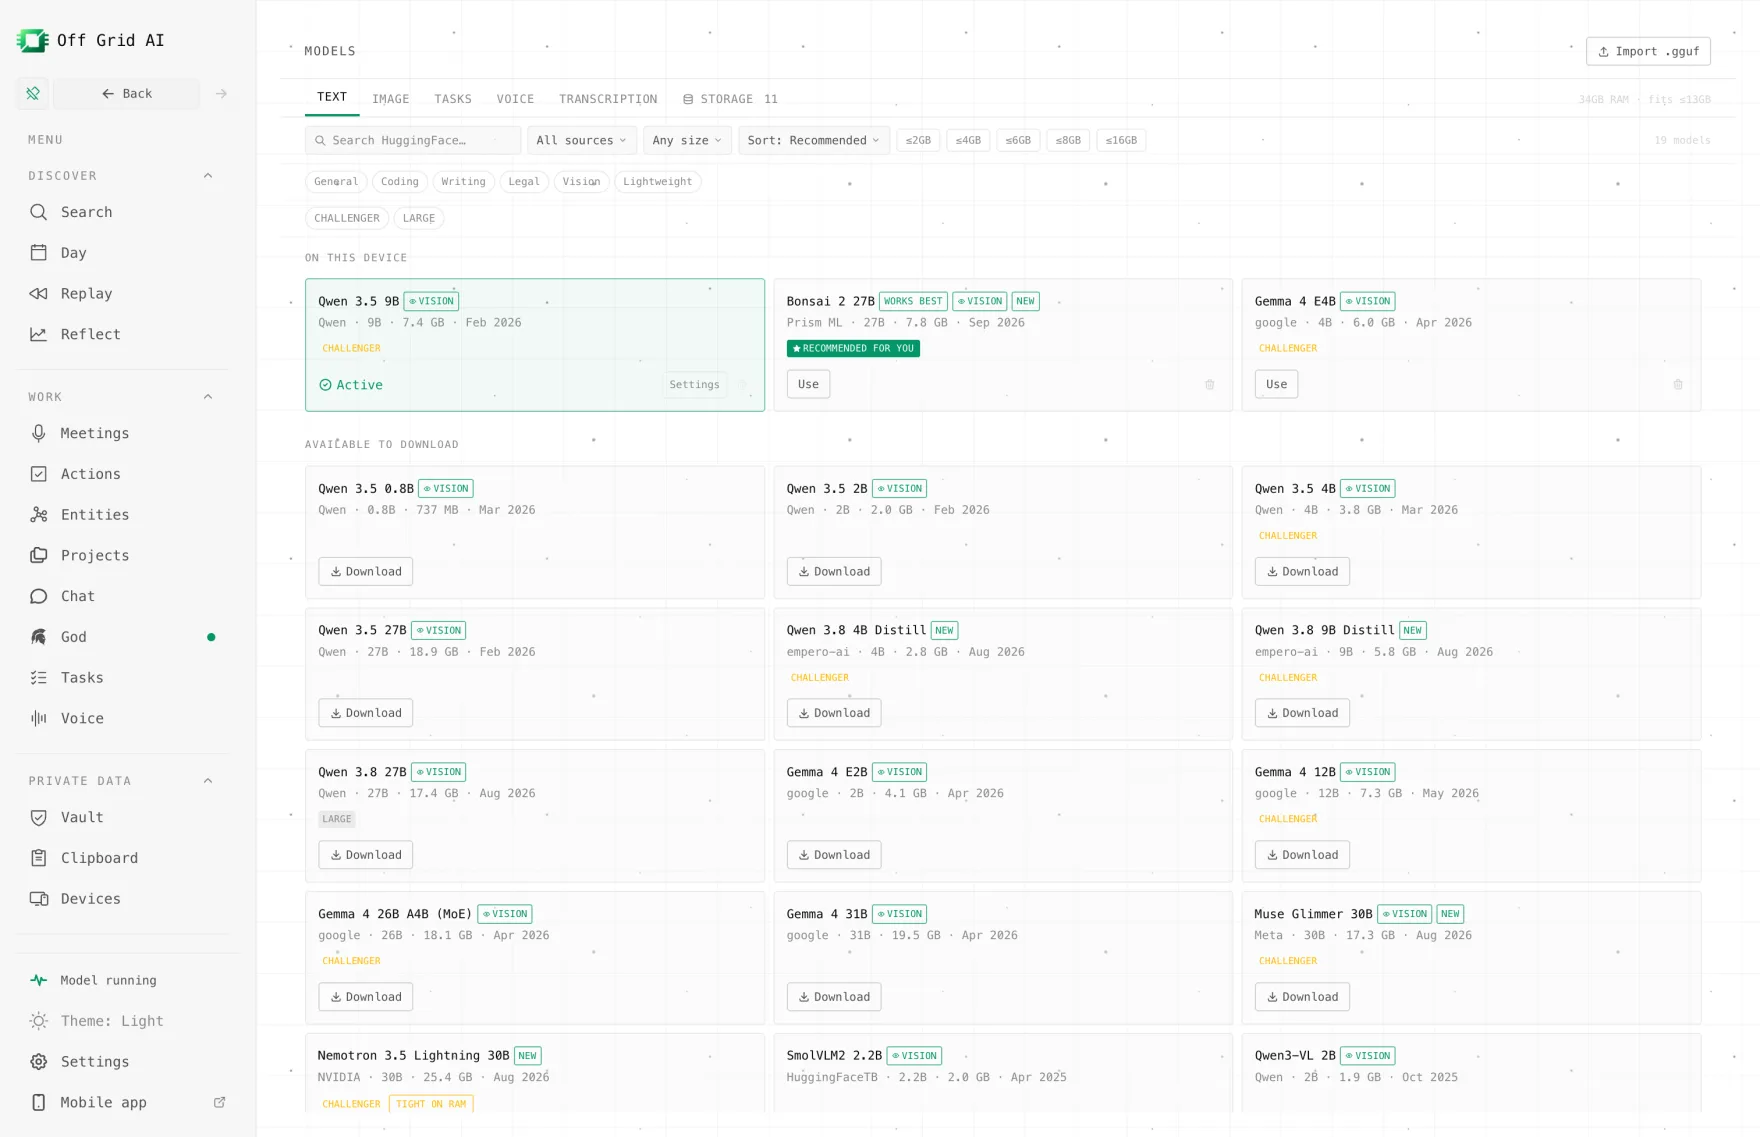
What fits your Mac
Off Grid AI Desktop checks every download against your Mac’s memory. A model up to 65% of your memory Runs well. Up to 82% it’s Tight, which means it loads but leaves little room for long chats. Past that it’s Too big.
A mixture-of-experts model gets no discount here. All 35B parameters have to fit, even though only 3B work at a time. Sizes below include the 0.9 GB vision file.
| Your Mac | File to use | Size | What the app shows |
|---|---|---|---|
| 16 GB | 1-bit UD-IQ1_M only | 11.0 GB | Tight, and 1-bit costs quality. Use Qwen 3.8 27B as Bonsai 2 instead |
| 24 GB | 3-bit UD-IQ3_XXS | 14.1 GB | Runs well |
| 24 GB | 4-bit UD-IQ4_XS | 18.6 GB | Tight |
| 32 GB | 4-bit UD-IQ4_XS | 18.6 GB | Runs well |
| 32 GB | 4-bit UD-Q4_K_M (the app’s default) | 23.0 GB | Tight |
| 36 GB | 4-bit UD-Q4_K_M (the app’s default) | 23.0 GB | Runs well |
| 48 GB | 6-bit UD-Q6_K | 30.2 GB | Runs well |
| 64 GB or more | 8-bit Q8_0 | 37.8 GB | Runs well |
File sizes come from Unsloth’s Qwen 3.6 35B-A3B files. The verdicts are the app’s own rule applied to those sizes. The app’s catalog lists its default download for 32 GB and up, and on exactly 32 GB that file reads Tight, so a smaller 4-bit file is the better pick there.
What Qwen 3.6 35B-A3B is
Qwen 3.6 35B-A3B is Alibaba’s April 2026 mixture-of-experts model, under the Apache 2.0 licence. It has 256 experts and uses 8 of them, plus one shared expert, for each token. That’s how 35B parameters run at the cost of about 3B.
It reads images, thinks before it answers by default, and handles 262,144 tokens of context natively.
On a Mac, Off Grid AI Desktop runs it through llama.cpp on Metal. Apple silicon shares one pool of memory between the CPU and GPU, so the whole model sits where the GPU can reach it.
Qwen 3.6 35B-A3B or Qwen 3.8 27B?
Both fit the same Macs, so this is the real choice.
- Qwen 3.8 27B is newer and scores much higher in the app’s own quality ranking. It’s a dense model, so every parameter works on every token, which makes it slower.
- Qwen 3.6 35B-A3B replies faster, because only 3B parameters work per token. It’s the one to pick for quick back-and-forth, drafts and tool calls where you’d rather not wait.
If you’re not sure, try Qwen 3.6 first for speed, and switch to Qwen 3.8 27B when an answer needs more care.
How to set it up
- Download Off Grid AI Desktop, install it and open it.
- Open Models > Text and type Qwen 3.6 in Search models….
- Click the Qwen 3.6 35B A3B card. It carries a MoE · 3B active tag.
- Pick the size for your Mac:
- 36 GB or more: choose Download for the standard 4-bit file.
- 24 or 32 GB: under Sizes, pick the file from the table above. All files shows every size. Skip any marked Tight or Too big.
- Wait for the model and its vision file to finish. That’s 14 to 23 GB, so use a fast connection.
- Open a new chat, select Qwen 3.6 35B A3B and ask something you can check.
The card may also show Newer: Sage A1.5 35B. That’s the app suggesting a different 35B model. Qwen 3.6 still downloads and runs.
Try a task where speed shows:
Give me five subject lines for an email telling customers our office is closed on Friday. Keep each under eight words.
Then attach a screenshot or photo and ask about it. Turn off Wi-Fi and ask again. It keeps answering, because nothing leaves your Mac.
Keep it fast
- Leave memory free. Close heavy apps while it answers.
- Start a new chat per topic. A long history uses memory on every reply.
- Lower the context if it struggles. Open the model’s settings and reduce Context window. Qwen suggests long contexts for hard thinking tasks, but most chats don’t need them, and a Mac has less room than a server.
- Pick Runs well over Tight. A 4-bit file that fits beats a bigger one that runs out of room mid-chat.
If something goes wrong
| Symptom | Check | Fix |
|---|---|---|
| Qwen 3.6 isn’t in the list | Search | Type Qwen 3.6 in Search models… |
| The card says Too big or Tight | Your Mac’s memory | Pick a smaller file in Sizes, using the table above |
| Replies get slow in long chats | Context window | Lower it, or start a new chat |
| Your Mac slows down while it answers | Other apps using memory | Close them, or go one size down |
| Image questions fail | The vision file | Check it finished downloading |
| Download stops | Free disk space | Free up at least 25 GB for the standard 4-bit file |
Need the full-size model?
On a 16 GB Mac, Qwen 3.6 35B-A3B only fits at 1-bit. Run Qwen 3.8 27B as Bonsai 2 there, or use Off Grid AI Boost, a flat-price API for open models on our GPUs. Boost names Qwen 3.8 and DeepSeek V4.1 Flash on its list, not Qwen 3.6. It’s from $4.99 a month for the first cohort, and we don’t store your prompts or train on them. Boost starts in January; pre-order to lock in half price. Usage limits aren’t published yet.
FAQ
How much memory does Qwen 3.6 35B-A3B need on a Mac? 24 GB for a 3-bit file of about 14 GB, 32 GB for a 4-bit file of about 19 GB, and 36 GB for the standard 4-bit download of 23 GB, all with the vision file. On 16 GB only the 1-bit file fits, and only just.
Why is Qwen 3.6 35B-A3B fast? It’s a mixture-of-experts model. All 35B parameters sit in memory, but only about 3B work on each token. Off Grid AI Desktop describes it as needing the memory of 35B and running at the speed of 3B.
Should I run Qwen 3.6 35B-A3B or Qwen 3.8 27B? Qwen 3.8 27B scores higher in the app’s own quality ranking. Qwen 3.6 35B-A3B replies faster on the same Mac. Pick 3.8 for the best answers and 3.6 when speed matters more.
Does it work offline? Yes. After the download, it runs on your Mac with Wi-Fi off, and your chats stay on your disk.
Can it read images? Yes. It has a 0.9 GB vision file, and Off Grid AI Desktop downloads it with the model. Attach an image to the chat and ask about it.
Related guides
- How to Run Qwen 3.8 27B on Your Mac in 2026
- How to Run Qwen 3.5 on Your Mac in 2026
- What Mac Do You Need to Run Qwen 3.8 or DeepSeek in 2026?
- How to Run Qwen Locally on Your Computer in 2026
Download Off Grid AI Desktop and run Qwen 3.6 35B-A3B on your Mac today.