

On this page
Qwen 3.6 runs on a 16 GB laptop, but only as a 2-bit file. Off Grid AI Desktop runs Qwen 3.6 27B as a 9.4 GB file or 35B-A3B as a 10.1 GB file on a 16 GB Mac, Windows or Linux laptop, free and offline. For better answers at a smaller size, use Bonsai 2 27B, a 7.2 GB build of the newer Qwen 3.8 27B.
The usual 4-bit Qwen 3.6 files are 16.8 GB and 22.1 GB. Neither fits in 16 GB of RAM.
Download Off Grid AI Desktop (free, Mac, Windows and Linux)
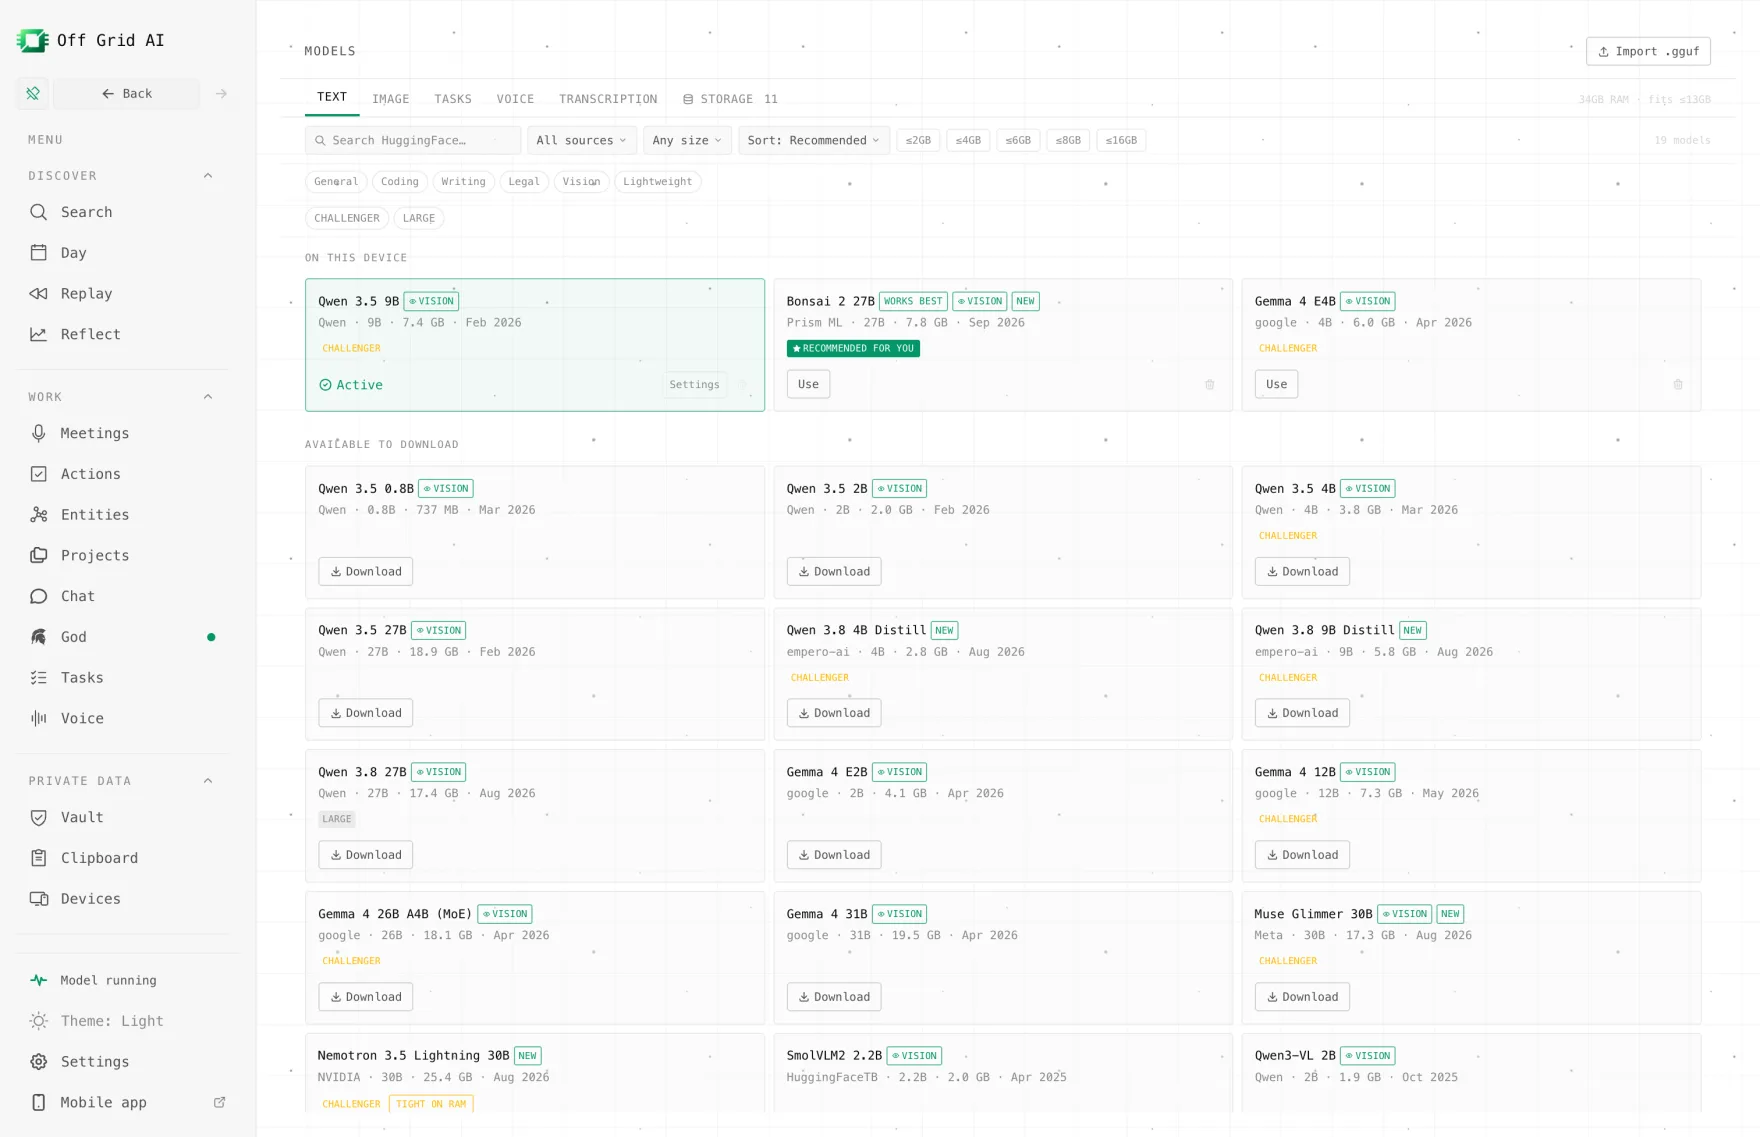
Which Qwen 3.6 file fits in 16 GB?
Alibaba released two open Qwen 3.6 models in April 2026, both under Apache 2.0 with a 262K context and vision built in (27B card, 35B-A3B card). The 27B is dense, so every parameter works on every word. The 35B-A3B is a mixture of experts with 3B active per word, so it answers faster but needs more memory to hold.
Off Grid AI Desktop judges fit by file size against your RAM. Up to 65% runs well, up to 82% is Tight, and past that it’s Too big. On 16 GB that means under 10.4 GB runs well and up to 13.1 GB is Tight.
| File (Unsloth) | Size | On 16 GB |
|---|---|---|
| 27B UD-IQ2_XXS (2-bit) | 9.4 GB | Runs well |
| 27B UD-IQ2_M (2-bit) | 10.9 GB | Tight |
| 27B UD-IQ3_XXS (3-bit) | 12.0 GB | Tight, little room for context |
| 27B Q4_K_M (4-bit) | 16.8 GB | Too big |
| 35B-A3B UD-IQ1_M (1-bit) | 10.1 GB | Runs well |
| 35B-A3B UD-IQ2_M (2-bit) | 11.5 GB | Tight |
| 35B-A3B UD-Q2_K_XL (2-bit) | 12.3 GB | Tight |
| 35B-A3B UD-Q4_K_M (in the app’s list) | 22.1 GB | Too big. The app lists it for 32 GB |
| Bonsai 2 27B (Qwen 3.8 27B, in the app’s list) | 7.2 GB | Runs well. The app lists it for 16 GB |
Sizes are from Unsloth’s 27B and 35B-A3B file lists and the app’s catalog, checked 16 November 2026. The table judges the model file alone. Image questions add a 0.9 GB vision file, which can push a file near the line up one step.
A 1-bit or 2-bit file is a heavy squeeze. It loses more quality than the 4-bit version, and how much that matters depends on your work. Try it on a task you can check.
Should you run Qwen 3.6 or Qwen 3.8 on 16 GB?
For most people, Qwen 3.8. When you search for Qwen 3.6 27B in Off Grid AI Desktop, the app marks it Newer: Qwen 3.8 27B, because Qwen 3.8 27B does the same job better.
On 16 GB the newer model also fits better. Bonsai 2 27B is Prism ML’s 7.2 GB build of Qwen 3.8 27B, and Prism ML says it keeps 98.2% of the full model’s benchmark score. That leaves room for your browser and a longer chat.
Pick Qwen 3.6 when you need it in particular: to match results from another machine, or because you like the 35B-A3B’s speed. The app shows that model with an MoE · 3B active tag, so you know why it’s quick.
How to run Qwen 3.6 with Off Grid AI Desktop
- Download Off Grid AI Desktop and install it.
- Open Models and type Qwen3.6-27B or Qwen3.6-35B-A3B into Search models….
- Open the Unsloth upload and pick a file from the table. The app shows each file’s size and marks it Tight or Too big for your laptop.
- Start a new chat and pick the model.
- In Model settings, keep the Context window modest, such as 8,000 tokens. On 16 GB, every extra token of context costs memory.
To use Bonsai 2 27B instead, download it from Models > Text. On a 16 GB machine in the default Balanced mode, first-run setup often picks it for you.
A good test for either model:
Here’s a Python function that should merge two sorted lists, but it drops the last item sometimes. Find the bug and fix it.
Qwen 3.6 thinks before it answers by default, so the first reply takes a little longer. Once the file is downloaded, everything runs on your laptop with no internet.
What goes wrong, and the fix
| Symptom | Check | Fix |
|---|---|---|
| Laptop swaps or freezes on load | Other apps open | Quit browsers and heavy apps, or use a smaller file |
| Answers have odd mistakes | You’re on a 1-bit or 2-bit file | Try Bonsai 2 27B, or a 3-bit file if you have room |
| Slow in long chats | Context window in Model settings | Lower it, or start a new chat per topic |
| The 22.1 GB 35B-A3B in the app’s list is Too big | It’s listed for 32 GB | Search for a 2-bit file instead |
| Image questions fail | The 0.9 GB vision file | Leave memory free for it, or use a smaller file |
Need the full-size model?
At full size, Qwen 3.6 27B is about 54 GB and 35B-A3B about 69 GB, so no 16 GB laptop comes close. If you want a full-size Qwen without buying a 64 GB machine, Off Grid AI Boost is a flat-price API for open models on our GPUs, with Qwen 3.8, Qwen 3.6’s successor, and DeepSeek V4.1 Flash on the list.
Boost starts at $4.99 a month for the first cohort, with regular prices from $9.99 to $199.99. We don’t store your prompts or train on them. That’s our promise today, and the full policy comes with launch. Usage limits aren’t published yet.
Boost starts in January; pre-order to lock in half price. API keys arrive by January 2027.
FAQ
Can Qwen 3.6 run on a laptop with 16 GB of RAM? Yes, as a 2-bit file. Qwen 3.6 27B UD-IQ2_XXS (9.4 GB) and 35B-A3B UD-IQ1_M (10.1 GB) run well on 16 GB by Off Grid AI Desktop’s fit rule. Files up to about 13 GB are Tight. The usual 4-bit files are 16.8 and 22.1 GB and won’t fit.
Should I pick Qwen 3.6 27B or 35B-A3B on 16 GB? 35B-A3B if you want speed, because only 3B parameters work on each word. 27B if you want the stronger dense model and can wait. On 16 GB both are 2-bit, so both lose some quality.
Is there something better than Qwen 3.6 for 16 GB? Bonsai 2 27B. It’s a 7.2 GB build of Qwen 3.8 27B, Qwen 3.6 27B’s successor, and Off Grid AI Desktop lists it for 16 GB of RAM.
How much RAM does Qwen 3.6 need at 4-bit? Off Grid AI Desktop lists Qwen 3.6 35B A3B’s 22.1 GB 4-bit file for 32 GB of RAM. The 27B’s 16.8 GB Q4_K_M runs well from 32 GB and is Tight on 24 GB.
Does Qwen 3.6 read images on a laptop? Yes. Both models read images through a separate 0.9 GB vision file, which loads only when you send a picture.
Related guides
- How to Run Qwen 3.8 Privately on a 16GB Laptop in 2026
- What Can You Do With Local AI on a 16 GB Laptop in 2026?
- How to Run gpt-oss-20b on a 16GB Laptop in 2026
- How to Run Qwen Locally on Your Computer in 2026
Download Off Grid AI Desktop, try Bonsai 2 27B first, and pull a 2-bit Qwen 3.6 only if you need that model in particular.